DeepSeek V4 - almost on the frontier, a fraction of the price
Tracking the history of the now-deceased OpenAI Microsoft AGI clause
LLM 0.32a0 is a major backwards-compatible refactor
Plus 9 links and 4 quotations and 2 notes and 5 beats
Sponsor message:MongoDB.local London on 7 May is for builders, founders, and AI teams serious about getting from pilot to production. Hear from 20VC, ElevenLabs, and Sequoia Capital on how to ship AI that actually works in the real world.
Chinese AI lab DeepSeek’s last model release was V3.2 (and V3.2 Speciale) last December. They just dropped the first of their hotly anticipated V4 series in the shape of two preview models, DeepSeek-V4-Pro and DeepSeek-V4-Flash.
Both models are 1 million token context Mixture of Experts. Pro is 1.6T total parameters, 49B active. Flash is 284B total, 13B active. They’re using the standard MIT license.
I think this makes DeepSeek-V4-Pro the new largest open weights model. It’s larger than Kimi K2.6 (1.1T) and GLM-5.1 (754B) and more than twice the size of DeepSeek V3.2 (685B).
Pro is 865GB on Hugging Face, Flash is 160GB. I’m hoping that a lightly quantized Flash will run on my 128GB M5 MacBook Pro. It’s possiblethe Pro model may run on it if I can stream just the necessary active experts from disk.
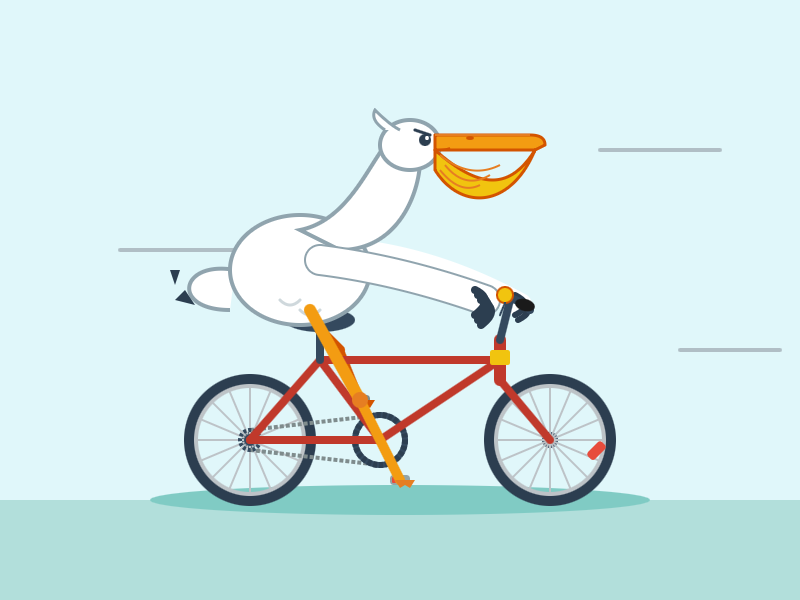
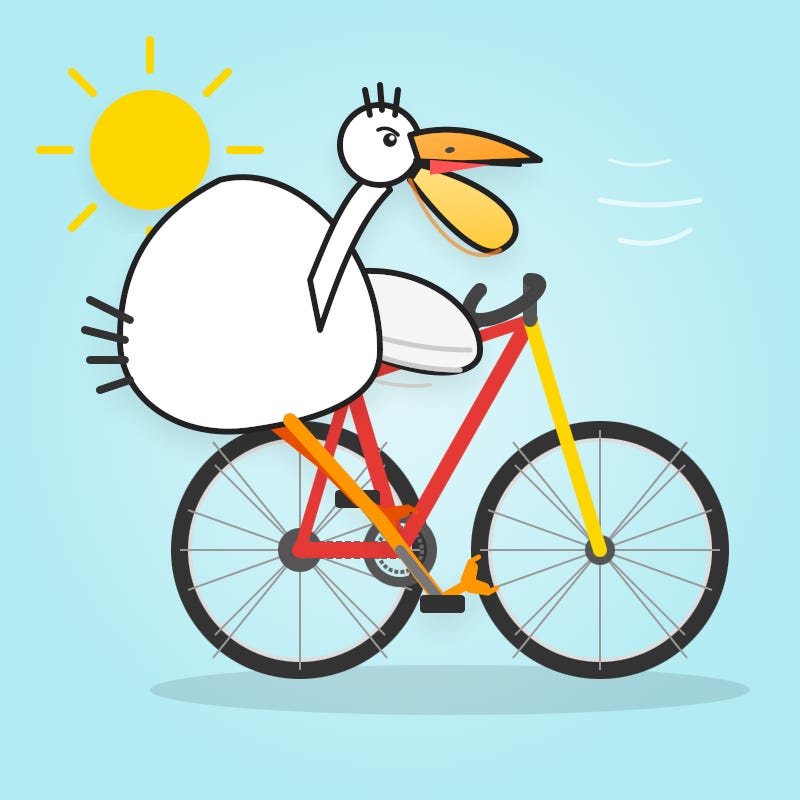
So the pelicans are pretty good, but what’s really notable here is the cost. DeepSeek V4 is a very, very inexpensive model.
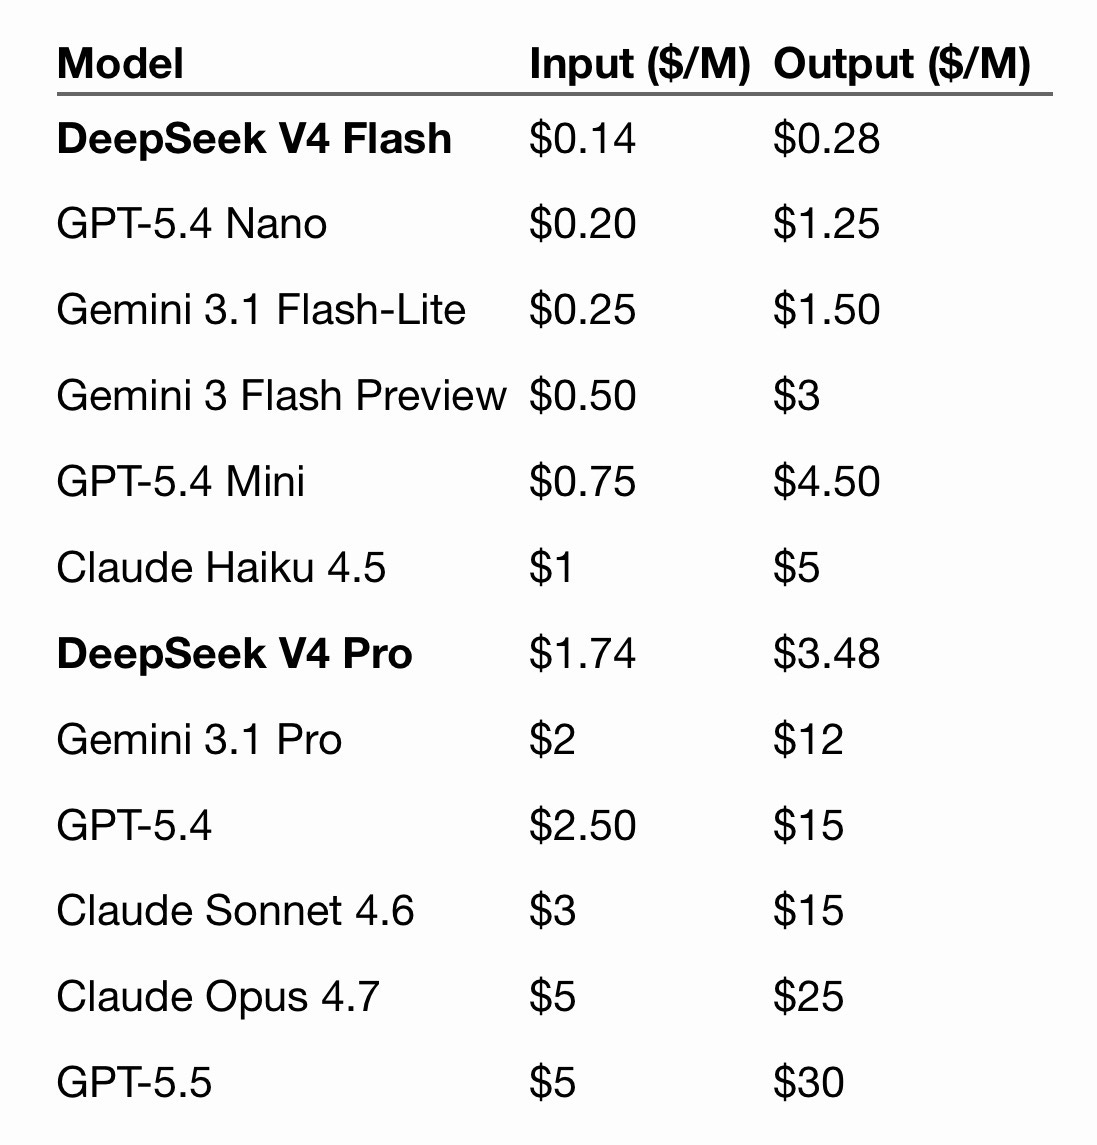
This is DeepSeek’s pricing page. They’re charging $0.14/million tokens input and $0.28/million tokens output for Flash, and $1.74/million input and $3.48/million output for Pro.
Here’s a comparison table with the frontier models from Gemini, OpenAI and Anthropic:
DeepSeek-V4-Flash is the cheapest of the small models, beating even OpenAI’s GPT-5.4 Nano. DeepSeek-V4-Pro is the cheapest of the larger frontier models.
This note from the DeepSeek paper helps explain why they can price these models so low - they’ve focused a great deal on efficiency with this release, especially for longer context prompts:
In the scenario of 1M-token context, even DeepSeek-V4-Pro, which has a larger number of activated parameters, attains only 27% of the single-token FLOPs (measured in equivalent FP8 FLOPs) and 10% of the KV cache size relative to DeepSeek-V3.2. Furthermore, DeepSeek-V4-Flash, with its smaller number of activated parameters, pushes efficiency even further: in the 1M-token context setting, it achieves only 10% of the single-token FLOPs and 7% of the KV cache size compared with DeepSeek-V3.2.
DeepSeek’s self-reported benchmarks in their paper show their Pro model competitive with those other frontier models, albeit with this note:
Through the expansion of reasoning tokens, DeepSeek-V4-Pro-Max demonstrates superior performance relative to GPT-5.2 and Gemini-3.0-Pro on standard reasoning benchmarks. Nevertheless, its performance falls marginally short of GPT-5.4 and Gemini-3.1-Pro, suggesting a developmental trajectory that trails state-of-the-art frontier models by approximately 3 to 6 months.
I’m keeping an eye on huggingface.co/unsloth/models as I expect the Unsloth team will have a set of quantized versions out pretty soon. It’s going to be very interesting to see how well that Flash model runs on my own machine.
For many years, Microsoft and OpenAI’s relationship has included a weird clause saying that, should AGI be achieved, Microsoft’s commercial IP rights to OpenAI’s technology would be null and void. That clause appeared to end today. I decided to try and track its expression over time on openai.com.
OpenAI is producing a sequence of increasingly powerful AI technologies, which requires a lot of capital for computational power. The most obvious way to cover costs is to build a product, but that would mean changing our focus. Instead, we intend to license some of our pre-AGI technologies, with Microsoft becoming our preferred partner for commercializing them.
OpenAI’s mission is to ensure that artificial general intelligence (AGI)—by which we mean highly autonomous systems that outperform humans at most economically valuable work—benefits all of humanity.
Here’s the problem: if you’re going to sign an agreement with Microsoft that is dependent on knowing when “AGI” has been achieved, you need something a little more concrete.
Last year’s agreement between Microsoft and OpenAI, which hasn’t been disclosed, said AGI would be achieved only when OpenAI has developed systems that have the ability to generate the maximum total profits to which its earliest investors, including Microsoft, are entitled, according to documents OpenAI distributed to investors. Those profits total about $100 billion, the documents showed.
So AGI is now whenever OpenAI’s systems are capable of generating $100 billion in profit?
The agreement preserves key elements that have fueled this successful partnership—meaning OpenAI remains Microsoft’s frontier model partner and Microsoft continues to have exclusive IP rights and Azure API exclusivity until Artificial General Intelligence (AGI). [...]
Once AGI is declared by OpenAI, that declaration will now be verified by an independent expert panel. [...]
Microsoft’s IP rights to research, defined as the confidential methods used in the development of models and systems, will remain until either the expert panel verifies AGI or through 2030, whichever is first.
AGI definition and processes are unchanged. The contractual definition of AGI and the process for determining if it has been achieved remains the same.
Microsoft will continue to have a license to OpenAI IP for models and products through 2032. Microsoft’s license will now be non-exclusive.
Microsoft will no longer pay a revenue share to OpenAI.
Revenue share payments from OpenAI to Microsoft continue through 2030, independent of OpenAI’s technology progress, at the same percentage but subject to a total cap.
As far as I can tell “independent of OpenAI’s technology progress” is a declaration that the AGI clause is now dead. Here’s The Verge coming to the same conclusion: The AGI clause is dead.
My all-time favorite commentary on OpenAI’s approach to AGI remains this 2023 hypothetical by Matt Levine:
And the investors wailed and gnashed their teeth but it’s true, that is what they agreed to, and they had no legal recourse. And OpenAI’s new CEO, and its nonprofit board, cut them a check for their capped return and said “bye” and went back to running OpenAI for the benefit of humanity. It turned out that a benign, carefully governed artificial superintelligence is really good for humanity, and OpenAI quickly solved all of humanity’s problems and ushered in an age of peace and abundance in which nobody wanted for anything or needed any Microsoft products. And capitalism came to an end.
I just released LLM 0.32a0, an alpha release of my LLM Python library and CLI tool for accessing LLMs, with some consequential changes that I’ve been working towards for quite a while.
Previous versions of LLM modeled the world in terms of prompts and responses. Send the model a text prompt, get back a text response.
import llm

model = llm.get_model(”gpt-5.5”)
response = model.prompt(”Capital of France?”)
print(response.text())
This made sense when I started working on the library back in April 2023. A lot has changed since then!
LLM provides an abstraction over thousands of different models via its plugin system. The original abstraction - of text input that returns text output - was no longer able to represent everything I needed it to.
Over time LLM itself has grown attachments to handle image, audio, and video input, then schemas for outputting structured JSON, then tools for executing tool calls. Meanwhile LLMs kept evolving, adding reasoning support and the ability to return images and all kinds of other interesting capabilities.
LLM needs to evolve to better handle the diversity of input and output types that can be processed by today’s frontier models.
The 0.32a0 alpha has two key changes: model inputs can be represented as a sequence of messages, and model responses can be composed of a stream of differently typed parts.
Prompts as a sequence of messages
LLMs accept input as text, but ever since ChatGPT demonstrated the value of a two-way conversational interface, the most common way to prompt them has been to treat that input as a sequence of conversational turns.
The first turn might look like this:
user: Capital of France?
assistant:
(The model then gets to fill out the reply from the assistant.)
But each subsequent turn needs to replay the entire conversation up to that point, as a sort of screenplay:
user: Capital of France?
assistant: Paris
user: Germany?
assistant:
Most of the JSON APIs from the major vendors follow this pattern. Here’s what the above looks like using the OpenAI chat completions API, which has been widely imitated by other providers:
This worked if you were building a conversation with the model from scratch, but it didn’t provide a way to feed in a previous conversation from the start. This made tasks like building an emulation of the OpenAI chat completions API much harder than they should have been.
The llm CLI tool worked around this through a custom mechanism for persisting and inflating conversations using SQLite, but that never became a stable part of the LLM API - and there are many places you might want to use the Python library without committing to SQLite as the storage layer.
The new alpha now supports this:
import llm
from llm import user, assistant

model = llm.get_model(”gpt-5.5”)

response = model.prompt(messages=[
    user(”Capital of France?”),
    assistant(”Paris”),
    user(”Germany?”),
])
print(response.text())
The llm.user() and llm.assistant() functions are new builder functions designed to be used within that messages=[] array.
The previous prompt= option still works, but LLM upgrades it to a single-item messages array behind the scenes.
You can also now reply to a response, as an alternative to building a conversation:
The other major new interface in the alpha concerns streaming results back from a prompt.
Previously, LLM supported streaming like this:
response = model.prompt(”Generate an SVG of a pelican riding a bicycle”)
for chunk in response:
    print(chunk, end=”“)
Or this async variant:
import asyncio
import llm

model = llm.get_async_model(”gpt-5.5”)
response = model.prompt(”Generate an SVG of a pelican riding a bicycle”)

async def run():
    async for chunk in response:
        print(chunk, end=”“, flush=True)

asyncio.run(run())
Many of today’s models return mixed types of content. A prompt run against Claude might return reasoning output, then text, then a JSON request for a tool call, then more text content.
Some models can even execute tools on the server-side, for example OpenAI’s code interpreter tool or Anthropic’s web search. This means the results from the model can combine text, tool calls, tool outputs and other formats.
Multi-modal output models are starting to emerge too, which can return images or even snippets of audio intermixed into that streaming response.
The new LLM alpha models these as a stream of typed message parts. Here’s what that looks like as a Python API consumer:
import asyncio
import llm

model = llm.get_model(”gpt-5.5”)
prompt = “invent 3 cool dogs, first talk about your motivations”

def describe_dog(name: str, bio: str) -> str:
    “”“Record the name and biography of a hypothetical dog.”“”
    return f”{name}: {bio}”

def sync_example():
    response = model.prompt(
        prompt,
        tools=[describe_dog],
    )
    for event in response.stream_events():
        if event.type == “text”:
            print(event.chunk, end=”“, flush=True)
        elif event.type == “tool_call_name”:
            print(f”\nTool call: {event.chunk}(”, end=”“, flush=True)
        elif event.type == “tool_call_args”:
            print(event.chunk, end=”“, flush=True)

async def async_example():
    model = llm.get_async_model(”gpt-5.5”)
    response = model.prompt(
        prompt,
        tools=[describe_dog],
    )
    async for event in response.astream_events():
        if event.type == “text”:
            print(event.chunk, end=”“, flush=True)
        elif event.type == “tool_call_name”:
            print(f”\nTool call: {event.chunk}(”, end=”“, flush=True)
        elif event.type == “tool_call_args”:
            print(event.chunk, end=”“, flush=True)

sync_example()
asyncio.run(async_example())
Sample output (from just the first sync example):
My motivation: create three memorable dogs with distinct “cool” styles—one cinematic, one adventurous, and one charmingly chaotic—so each feels like they could star in their own story. Tool call: describe_dog({"name": "Nova Jetpaw", "bio": "A sleek silver-gray whippet who wears tiny aviator goggles and loves sprinting along moonlit beaches. Nova is fearless, elegant, and rumored to outrun drones just for fun."} Tool call: describe_dog({"name": "Mochi Thunderbark", "bio": "A fluffy corgi with a dramatic black-and-gold bandana and the confidence of a rock star. Mochi is short, loud, loyal, and leads a neighborhood 'security patrol' made entirely of squirrels."} Tool call: describe_dog({"name": "Atlas Snowfang", "bio": "A massive white husky with ice-blue eyes and a backpack full of trail snacks. Atlas is calm, heroic, and always knows the way home—even during blizzards, fog, or confusing camping trips."}
At the end of the response you can call response.execute_tool_calls() to actually run the functions that were requested, or send a response.reply() to have those tools called and their return values sent back to the model:
print(response.reply(”Tell me about the dogs”))
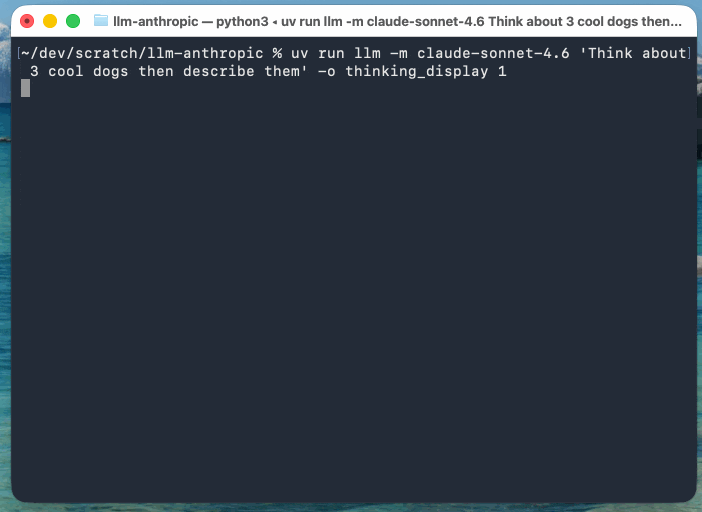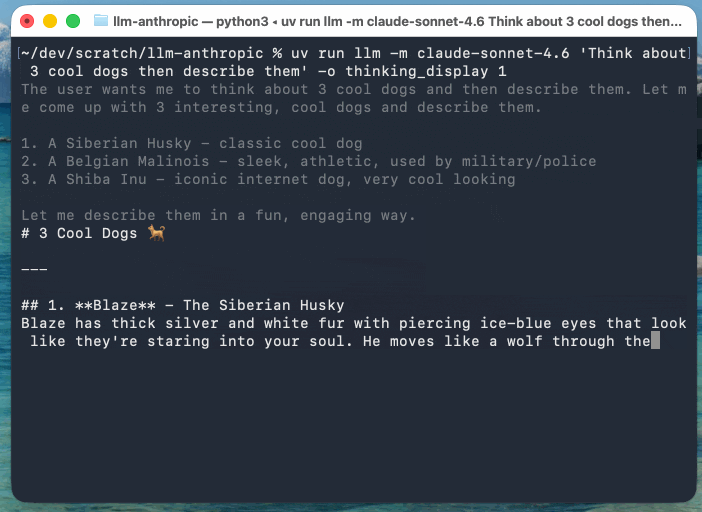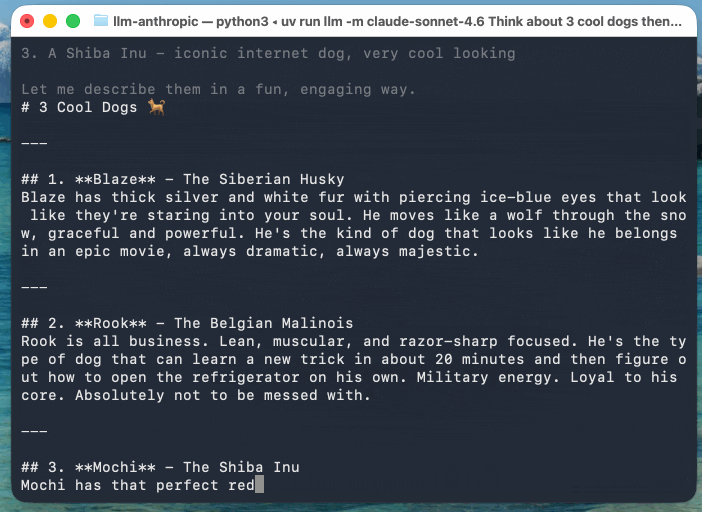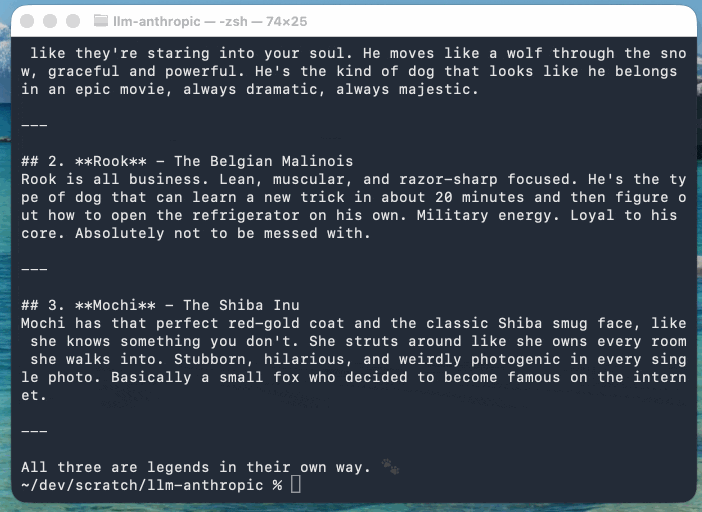
This new mechanism for streaming different token types means the CLI tool can now display “thinking” text in a different color from the text in the final response. The thinking text goes to stderr so it won’t affect results that are piped into other tools.
This example uses Claude Sonnet 4.6 (with an updated streaming event version of the llm-anthropic plugin) as Anthropic’s models return their reasoning text as part of the response:
llm -m claude-sonnet-4.6 ‘Think about 3 cool dogs then describe them’ \
  -o thinking_display 1
You can suppress the output of reasoning tokens using the new -R/--no-reasoning flag. Surprisingly that ended up being the only CLI-facing change in this release.
A mechanism for serializing and deserializing responses
As mentioned earlier, LLM has quite inflexible code at the moment for persisting conversations to SQLite. I’ve added a new mechanism in 0.32a0 that should provide Python API users a way to roll their own alternative:
serializable = response.to_dict()
# serializable is a JSON-style dictionary
# store it anywhere you like, then inflate it:
response = Response.from_dict(serializable)
The dictionary this returns is actually a TypedDict defined in the new llm/serialization.py module.
What’s next?
I’m releasing this as an alpha so I can upgrade various plugins and exercise the new design in real world environments for a few days. I expect the stable 0.32 release will be very similar to this alpha, unless alpha testing reveals some design flaw in the way I’ve put this all together.
There’s one remaining large task: I’d like to redesign the SQLite logging system to better capture the more finely grained details that are returned by this new abstraction.
Ideally I’d like to model this as a graph, to best support situations like an OpenAI-style chat completions API where the same conversations are constantly extended and then repeated with every prompt. I want to be able to store those without duplicating them in the database.
I’m undecided as to whether that should be a feature in 0.32 or I should hold it for 0.33.
This written and video essay by Nilay Patel explores why AI is unpopular with the general public even as usage numbers for ChatGPT continue to skyrocket.
It’s a superb piece of commentary, and something I expect I’ll be thinking about for a long time to come.
Nilay’s core idea is that people afflicted with “software brain” - who see the world as something to be automated as much as possible, and attempt to model everything in terms of information flows and data - are becoming detached from everyone else.
[…] software brain has ruled the business world for a long time. AI has just made it easier than ever for more people to make more software than ever before — for every kind of business to automate big chunks of itself with software. It’s everywhere: the absolute cutting edge of advertising and marketing is automation with AI. It’s not being a creative.
But: not everything is a business. Not everything is a loop! The entire human experience cannot be captured in a database. That’s the limit of software brain. That’s why people hate AI. It flattens them.
Regular people don’t see the opportunity to write code as an opportunity at all. The people do not yearn for automation. I’m a full-on smart home sicko; the lights and shades and climate controls of my house are automated in dozens of ways. But huge companies like Apple, Google and Amazon have struggled for over a decade now to make regular people care about smart home automation at all. And they just don’t.
New option to set the text verbosity level for GPT-5+ OpenAI models: -o verbosity low. Values are low, medium, high.
New option for setting the image detail level used for image attachments to OpenAI models: -o image_detail low - values are low, high and auto, and GPT-5.4 and 5.5 also accept original.
Models listed in extra-openai-models.yaml are now also registered as asynchronous. #1395
Now that GPT-5.5 is available in the API, OpenAI have released a wealth of useful tips on how best to prompt the new model.
Here’s a neat trick they recommend for applications that might spend considerable time thinking before returning a user-visible response:
Before any tool calls for a multi-step task, send a short user-visible update that acknowledges the request and states the first step. Keep it to one or two sentences.
I’ve already noticed their Codex app doing this, and it does make longer running tasks feel less like the model has crashed.
OpenAI suggest running the following in Codex to upgrade your existing code using advice embedded in their openai-docs skill:
$openai-docs migrate this project to gpt-5.5
The upgrade guide the coding agent will follow is this one, which even includes light instructions on how to rewrite prompts to better fit the model.
To get the most out of GPT-5.5, treat it as a new model family to tune for, not a drop-in replacement for gpt-5.2 or gpt-5.4. Begin migration with a fresh baseline instead of carrying over every instruction from an older prompt stack. Start with the smallest prompt that preserves the product contract, then tune reasoning effort, verbosity, tool descriptions, and output format against representative examples.
Interesting to see OpenAI recommend starting from scratch rather than trusting that existing prompts optimized for previous models will continue to work effectively with GPT-5.5.
Quote 2026-04-25
Since GPT-5.4, we’ve unified Codex and the main model into a single system, so there’s no separate coding line anymore.
GPT-5.5 takes this further, with strong gains in agentic coding, computer use, and any task on a computer.
Romain Huet, confirming OpenAI won’t release a GPT-5.5-Codex model
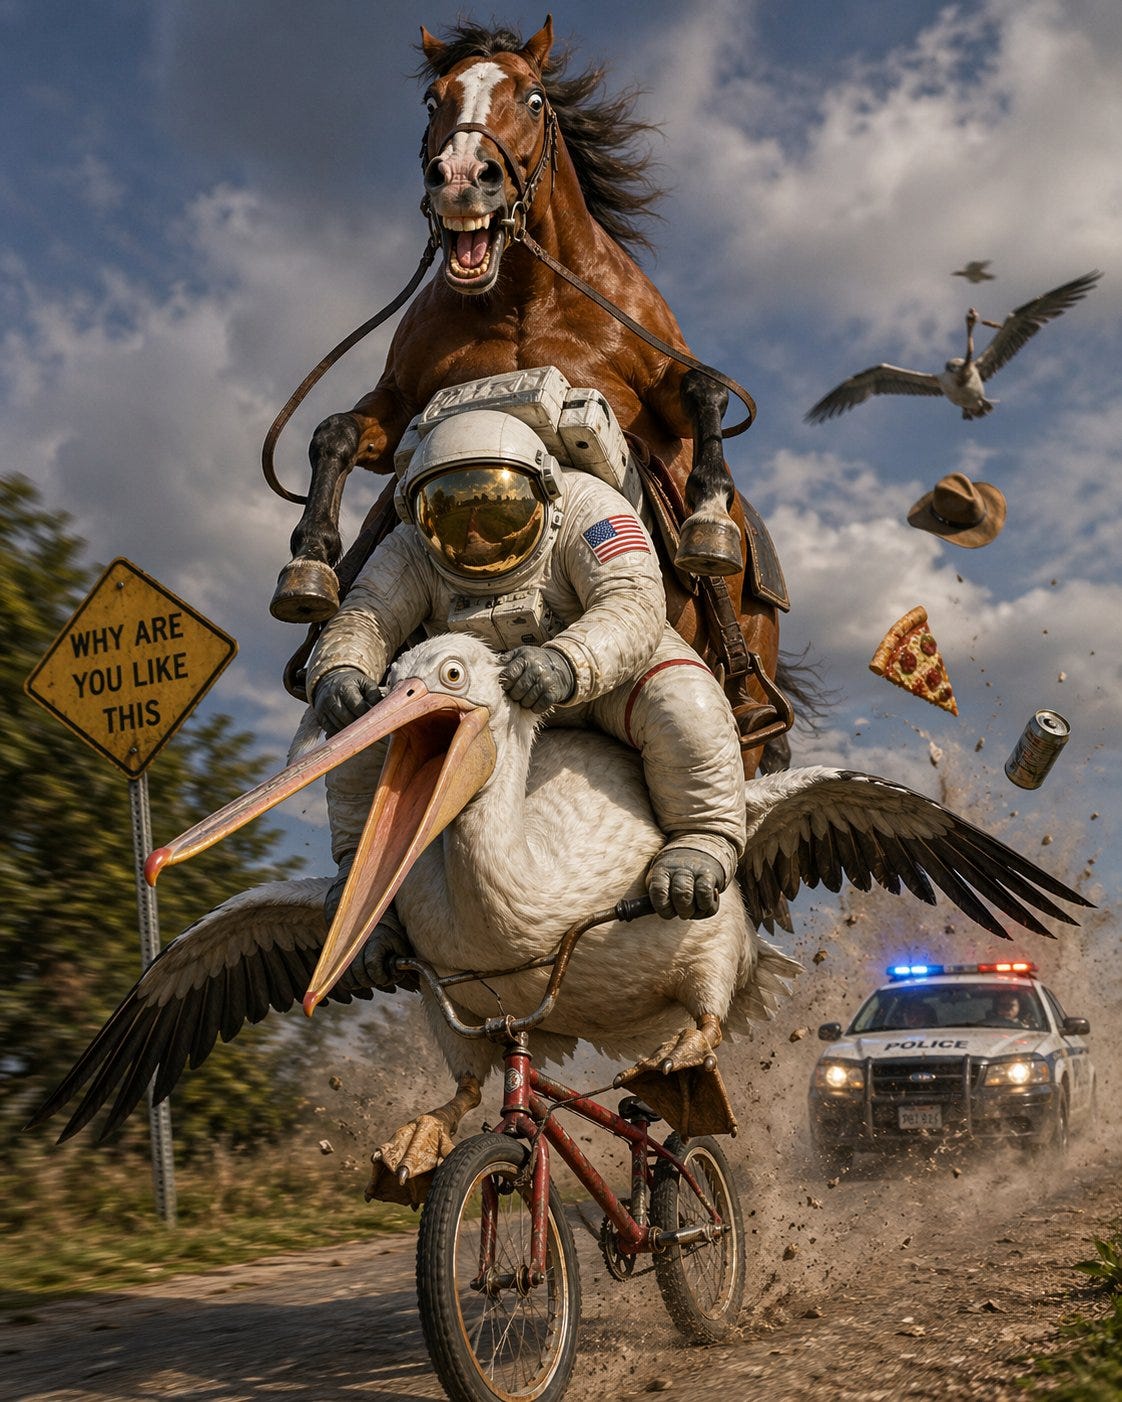
I checked to confirm that the model (ChatGPT Images 2.0) added the “WHY ARE YOU LIKE THIS” sign of its own accord and it did - the prompt Scott used was:
Create an image of a horse riding an astronaut, where the astronaut is riding a pelican that is riding a bicycle. It looks very chaotic but they all just manage to balance on top of each other
I just encountered this feature via a “try this out now” prompt in a Google Meet meeting. It kind-of worked!
This is Google’s implementation of the ultimate sci-fi translation app, where two people can talk to each other in two separate languages and Meet translates from one to the other and - with a short delay - repeats the text in your preferred language, with a rough imitation of the original speaker’s voice.
It can only handle English, Spanish, French, German, Portuguese, and Italian at the moment. It’s also still very alpha - I ran it successfully between two laptops running web browsers, but then when I tried between an iPhone and an iPad it didn’t seem to work.
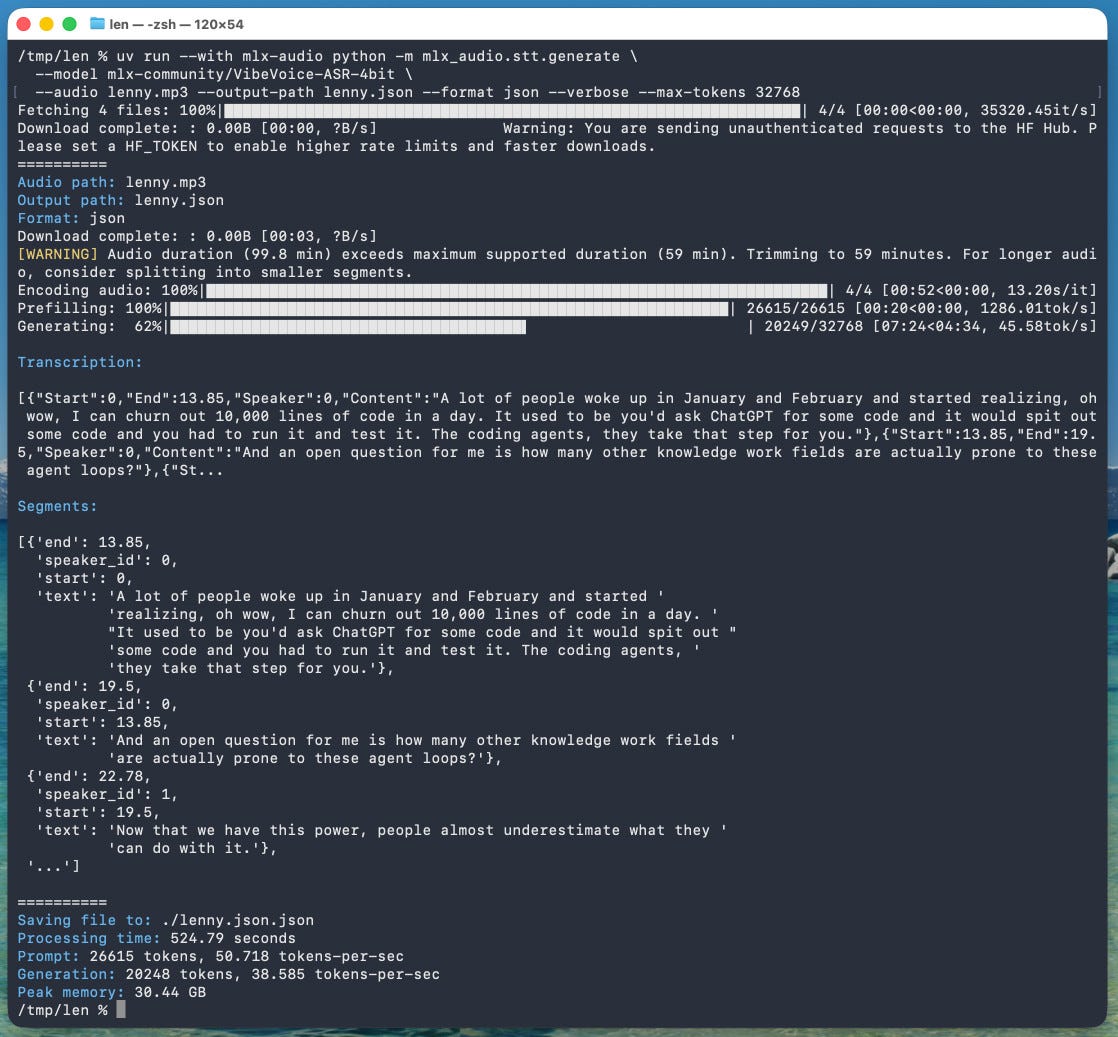
So that’s 8 minutes 45 seconds for an hour of audio (running on a 128GB M5 Max MacBook Pro).
I’ve tested it against .wav and .mp3 files and they both worked fine.
If you omit --max-tokens it defaults to 8192, which is enough for about 25 minutes of audio. I discovered that through trial-and-error and quadrupled it to guarantee I’d get the full hour.
That command reported using 30.44GB of RAM at peak, but in Activity Monitor I observed 61.5GB of usage during the prefill stage and around 18GB during the generating phase.
{
  "text": "And an open question for me is how many other knowledge work fields are actually prone to these agent loops?",
  "start": 13.85,
  "end": 19.5,
  "duration": 5.65,
  "speaker_id": 0
},
{
  "text": "Now that we have this power, people almost underestimate what they can do with it.",
  "start": 19.5,
  "end": 22.78,
  "duration": 3.280000000000001,
  "speaker_id": 1
},
{
  "text": "Today, probably 95% of the code that I produce, I didn't type it myself. I write so much of my code on my phone. It's wild.",
  "start": 22.78,
  "end": 30.0,
  "duration": 7.219999999999999,
  "speaker_id": 0
}
Amusingly that Datasette Lite view shows three speakers - it identified Lenny and me for the conversation, and then a separate Lenny for the voice he used for the additional intro and the sponsor reads!
VibeVoice can only handle up to an hour of audio, so running the above command transcribed just the first hour of the podcast. To transcribe more than that you’d need to split the audio, ideally with a minute or so of overlap so you can avoid errors from partially transcribed words at the split point. You’d also need to then line up the identified speaker IDs across the multiple segments.
talkie-1930-13b-base (53.1 GB) is a “13B language model trained on 260B tokens of historical pre-1931 English text”.
talkie-1930-13b-it (26.6 GB) is a checkpoint “finetuned using a novel dataset of instruction-response pairs extracted from pre-1931 reference works”, designed to power a chat interface. You can try that out here.
Both models are Apache 2.0 licensed. Since the training data for the base model is entirely out of copyright (the USA copyright cutoff date is currently January 1, 1931), I’m hoping they later decide to release the training data as well.
Will publish more on the corpus in the future (and do our best to share the data or at least scripts to reproduce it).
Their report suggests some fascinating research objectives for this class of model, including:
How good are these models at predicting the future? “we calculated the surprisingness of short descriptions of historical events to a 13B model trained on pre-1931 text”
Can these models invent things that are past their knowledge cutoffs? “As Demis Hassabis has asked, could a model trained up to 1911 independently discover General Relativity, as Einstein did in 1915?”
Can they be taught to program? “Figure 3 (left-hand side) shows an early example of such a test, measuring how well models trained on pre-1931 text can, when given a few demonstration examples of Python programs, write new correct programs.”
I have a long-running interest in what I call “vegan models” - LLMs that are trained entirely on licensed or out-of-copyright data. I think the base model here qualifies, but the chat model isn’t entirely pure due to the reliance on non-vegan models to help with the fine-tuning - emphasis mine:
First, we generated instruction-response pairs from historical texts with regular structure, such as etiquette manuals, letter-writing manuals, cookbooks, dictionaries, encyclopedias, and poetry and fable collections (see Figure 7), and fine-tuned our base model on them using a simple chat format.
Next, to improve instruction-following abilities, we generated synthetic prompts covering different types of tasks, such as summarizing documents, responding to direct information requests, and continuing multi-turn conversations coherently. We then ran online direct preference optimization on rollouts generated from these prompts, using Claude Sonnet 4.6 as a judge. [...]
Finally, we did another round of supervised fine-tuning, this time on rejection-sampled multi-turn synthetic chats between Claude Opus 4.6 and talkie, to smooth out persistent rough edges in its conversational abilities.
A major challenge in training talkie was avoiding accidental contamination, either from post-1931 text that snuck into the training corpus or from the fine-tuning assistance from modern LLMs introducing anachronistic knowledge to the chat model.
I recently wrote about Mr. Chatterbox, a similar vintage language model project which also had to turn to modern LLMs to create synthetic conversations to help train the chat model.
The talkie team aspire to eventually move beyond this limitation:
While we have tried to post-train talkie free from modern influence, reinforcement learning with AI feedback inevitably shapes talkie’s behavior anachronistically. (The 7B version of talkie emerged from RL speaking in listicles.) As we scale up, we hope to be able to use our vintage base models themselves as judges to enable a fully bootstrapped era-appropriate post-training pipeline.
I couldn’t resist hitting the talkie demo with my classic test prompt:
Generate an SVG of a pelican riding a bicycle
It replied:
An SVG of a pelican riding a bicycle was generated in 1860. The pelican was represented as perched on the saddle, with its long bill pointed forward, and its legs astride the handles. The idea was suggested by the fact that pelicans are sometimes seen fishing on horseback, on the banks of the Rhine.
Richard Si describes an excellent set of upgrades to Python’s default pip tool for installing dependencies.
This version drops support for Python 3.9 - fair enough, since it’s been EOL since October. macOS still ships with python3 as a default Python 3.9, so I tried out the new Python version against Python 3.14 like this:
This confirmed I had pip 26.1 - then I tried out the new lock files:
pip lock datasette llm
This installs Datasette and LLM and all of their dependencies and writes the whole lot to a 519 line pylock.toml file - here’s the result.
The new release also supports dependency cooldowns, discussed here previously, via the new --uploaded-prior-to PXD option where X is a number of days. The format is P-number-of-days-D, following ISO duration format but only supporting days.
I shipped a new release of LLM, version 0.31, three days ago. Here’s how to use the new --uploaded-prior-to P4D option to ask for a version that is at least 4 days old.
Five months in, I think I’ve decided that I don’t want to vibecode — I want professionally managed software companies to use AI coding assistance to make more/better/cheaper software products that they sell to me for money.
Never talk about goblins, gremlins, raccoons, trolls, ogres, pigeons, or other animals or creatures unless it is absolutely and unambiguously relevant to the user's query.
Zig has one of the most stringent anti-LLM policies of any major open source project:
No LLMs for issues.
No LLMs for pull requests.
No LLMs for comments on the bug tracker, including translation. English is encouraged, but not required. You are welcome to post in your native language and rely on others to have their own translation tools of choice to interpret your words.
The most prominent project written in Zig may be the Bun JavaScript runtime, which was acquired by Anthropic in December 2025 and, unsurprisingly, makes heavy use of AI assistance.
We do not currently plan to upstream this, as Zig has a strict ban on LLM-authored contributions.
(Update: here’s a Zig core contributorproviding details on why they wouldn’t accept that particular patch independent of the LLM issue - parallel semantic analysis is a long planned feature but has implications “for the Zig language itself”.)
In Contributor Poker and Zig’s AI Ban (via Lobste.rs) Zig Software Foundation VP of Community Loris Cro explains the rationale for this strict ban. It’s the best articulation I’ve seen yet for a blanket ban on LLM-assisted contributions:
In successful open source projects you eventually reach a point where you start getting more PRs than what you’re capable of processing. Given what I mentioned so far, it would make sense to stop accepting imperfect PRs in order to maximize ROI from your work, but that’s not what we do in the Zig project. Instead, we try our best to help new contributors to get their work in, even if they need some help getting there. We don’t do this just because it’s the “right” thing to do, but also because it’s the smart thing to do.
Zig values contributors over their contributions. Each contributor represents an investment by the Zig core team - the primary goal of reviewing and accepting PRs isn’t to land new code, it’s to help grow new contributors who can become trusted and prolific over time.
LLM assistance breaks that completely. It doesn’t matter if the LLM helps you submit a perfect PR to Zig - the time the Zig team spends reviewing your work does nothing to help them add new, confident, trustworthy contributors to their overall project.
Loris explains the name here:
The reason I call it “contributor poker” is because, just like people say about the actual card game, “you play the person, not the cards”. In contributor poker, you bet on the contributor, not on the contents of their first PR.
This makes a lot of sense to me. It relates to an idea I’ve seen circulating elsewhere: if a PR was mostly written by an LLM, why should a project maintainer spend time reviewing and discussing that PR as opposed to firing up their own LLM to solve the same problem?
I would love an RSS web feed for all those various tools and apps pages, each item with an “Install” button. (But install to where?)
The lesson here is that when vibe-coding accelerates app development, apps become more personal, more situated, and more frequent. Shipping a tool or a micro-app is less like launching a website and more like posting on a blog.
It’s a common misconception that we can’t tell who is using LLM and who is not. I’m sure we didn’t catch 100% of LLM-assisted PRs over the past few months, but the kind of mistakes humans make are fundamentally different than LLM hallucinations, making them easy to spot. Furthermore, people who come from the world of agentic coding have a certain digital smellthat is not obvious to them but is obvious to those who abstain. It’s like when a smoker walks into the room, everybody who doesn’t smoke instantly knows it.
I’m not telling you not to smoke, but I am telling you not to smoke in my house.
The UK’s AI Security Institute previously evaluated Claude Mythos: now they’ve evaluated GPT-5.5 for finding security vulnerability and found it to be comparable to Mythos, but unlike Mythos it’s generally available right now.
The latest version of OpenAI’s Codex CLI coding agent adds their own version of the Ralph loop: you can now set a /goal and Codex will keep on looping until it evaluates that the goal has been completed... or the configured token budget has been exhausted.
It looks like the feature is mainly implemented though the goals/continuation.md and goals/budget_limit.md prompts, which are automatically injected at the end of a turn.


wait, so does this mean the whole "AGI definition" thing was just a legal loophole for the funding? lol [language: en]